Budget build · open-frame · Used parts
Phoenix
10-year-old PC converted into an AI server
Built by @conoro · Source: @conoro on X · Updated
- Total cost
- $638
- VRAM
- 12GB
- GPUs
- 1
- System RAM
- 32GB
What can this build run?
With 12GB of VRAM across one GPU, this build comfortably runs models up to Phi-4 (Q3_K_M, ~34 tokens/sec). Our top all-round pick for it is Qwen3.5 9B at Q6_K (~30 tokens/sec).
Parts list
Every part in the Phoenix
We may earn a commission when you buy through links on this page. It never changes what we recommend. How we make money
| Part | Price | Buy |
|---|---|---|
GPU NVIDIA GeForce RTX 3060 12GB | $220 | eBay |
CPU Intel Core i7-4790 4-Core | $40 | eBay |
CPU Cooler Cooler Master Hyper 212 Black | $25 | Amazon |
Motherboard GIGABYTE GA-H87M-D3H mATX | $65 | eBay |
Memory Kingston HyperX Savage 32GB The original listing said DDR4, but the i7-4790 and H87 platform use DDR3. | $134 | eBay |
Storage Samsung 980 Pro 1TB M.2-2280 NVMe SSD | $89 | Amazon |
Case Custom test bench | — | |
Power Supply Thermaltake GX2 600W | $65 | Amazon |
| Total | $638 |
Prices at time of build (2025); check current prices.
Capability
Models this build runs well
Estimated for a single user with 8K context. Best quantization that fits, ranked by our capability score.
Best overall · also coding, reasoning, vision, fastest
Qwen3.5 9BQ6_K · ~30 tokens/sec
Largest model that fits
Phi-4Q3_K_M · ~34 tokens/sec
| Model | Quant | Speed | Fit |
|---|---|---|---|
| Qwen3.5 9B | Q6_K | ~30 tok/s | Runs well |
| Gemma 4 E4B | Q8_0 | ~27 tok/s | Runs well |
| Phi-4 | Q3_K_M | ~34 tok/s | Runs well |
The build
About this build
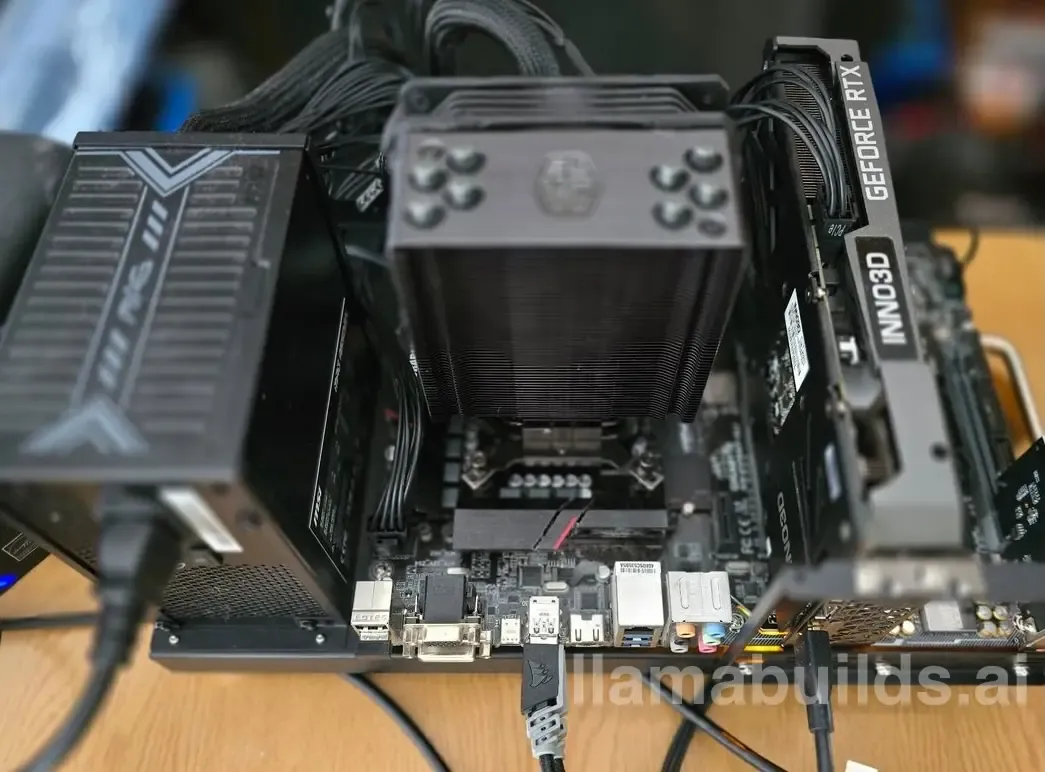
A 10-year-old Core i7 gaming PC gets a second life as a local AI server with an RTX 3060 12GB, Ubuntu, and LM Studio. A Cloudflare tunnel makes it reachable from a laptop or phone anywhere.
Why this build
I had this 10-year-old gaming PC sitting around with a decent i7 processor and 32GB of RAM, so I decided to give it new life as a local AI server. Best decision I’ve made in a while.
The key upgrade was adding an RTX 3060 12GB. I chose it over more powerful cards because of the 12GB of VRAM. It turns out memory matters way more than raw power for running AI models locally. Who knew?
I switched the whole thing to Ubuntu and went with an open-frame design, partly for better airflow around the new GPU. But honestly, it just looks cool sitting on my desk like some kind of tech art piece.
Software setup
LM Studio makes everything incredibly simple on Ubuntu 24.04. No command-line wizardry needed: just download models and run them. I’ve been testing Qwen3-4B-2507, and the speed is genuinely impressive. We’re talking near-instant responses, which makes chatting with local AI actually fun instead of frustrating.
The real game-changer was setting up a Cloudflare tunnel. Now I can access my AI server from my laptop, my phone, anywhere really. It’s like having my own private ChatGPT that runs on hardware I actually own.
Notes and caveats
- The Core i7-4790 and H87 motherboard support DDR3 memory only. If you reproduce this build, make sure the RAM you buy matches the platform.
Source
Originally shared by @conoro on X.
Specifications
Full specs
- GPU
- RTX 3060 12GB
- CPU
- Intel Core i7-4790 (4-core)
- Motherboard
- Gigabyte GA-H87M-D3H (mATX)
- Memory
- 32GB Kingston HyperX Savage
- Storage
- Samsung 980 Pro 1TB NVMe SSD
- Power supply
- Thermaltake GX2 600W
- Case
- Custom open test bench
- Cooling
- Cooler Master Hyper 212 Black
- Form factor
- open-frame
- GPU power
- 170W rated
Keep browsing